
It can be confusing when one sees that their backup host on SERVERware is showing storage usage very low, for example like here:

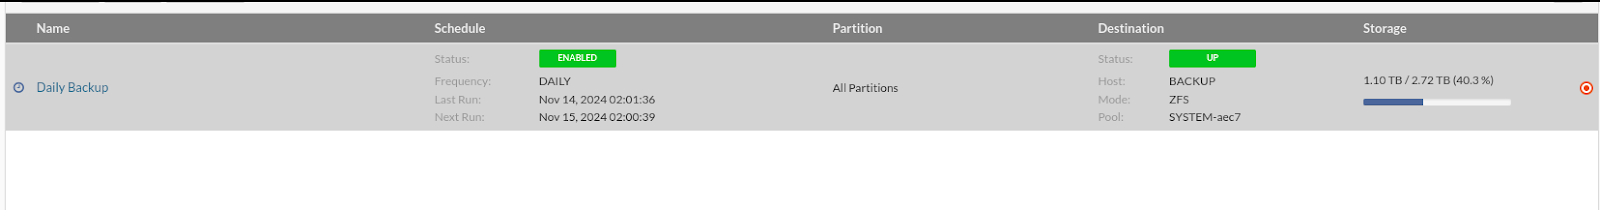
where Backup host is showing that only 1% of storage is being used on the Hosts page in SERVERware GUI, even though he sees that his backups are being done successfully every day and on the other side, Backup tab -> Schedule is showing different storage usage and for example you see like this:
Why is this the case?
If we take a closer look at the second picture, we will see that backup to ZFS is in question here.
Information shown on the first screenshot is the same information we will see if we ssh to the backup host in question and execute command
df -h
Which will show us something like this:
df -h
Filesystem Size Used Avail Use% Mounted on
devtmpfs 10M 0 10M 0% /dev
tmpfs 7.8G 0 7.8G 0% /dev/shm
tmpfs 7.8G 2.2M 7.8G 1% /run
SYSTEM-aec7/rootfs 834G 6.9G 827G 1% /
SYSTEM-aec7/rootfs/log 2.0G 135M 1.9G 7% /var/log
SYSTEM-aec7/BACKUP 1.6T 128K 1.6T 1% /BACKUP
overlayfs 7.8G 0 7.8G 0% /usr/portage
SYSTEM-aec7/backup-a7f78874dbbf4988b4789d49e3fab82f 1.6T 128K 1.6T 1% /SYSTEM-aec7/backup-a7f78874dbbf4988b4789d49e3fab82f
df is not a tool for displaying usage because we back up volumes, not datasets and as we are using Backup to ZFS, this would not show us actual results.
On the same host if you execute command:
zpool list
You will get information about storage usage which corresponds to the one which you see in GUI -> Backup -> Schedule

The zpool list command is used in ZFS to display information about all storage pools available on the system.
NAME: Name of the pool.
SIZE: Total size of the pool.
ALLOC: Amount of allocated (used) space in the pool.
FREE: Free space available in the pool.
CKPOINT: Indicates if a checkpoint exists for the pool.
EXPANDSZ: Size available for pool expansion (if applicable).
FRAG: Fragmentation percentage of the pool.
CAP: Percentage of pool capacity used.
DEDUP: Deduplication ratio for the pool.
HEALTH: Health status of the pool (e.g., ONLINE, DEGRADED, FAULTED).
ALTROOT: Alternate root directory, if configured.
The zfs list command is used to display information about ZFS datasets, including file systems, volumes, and snapshots on a system.
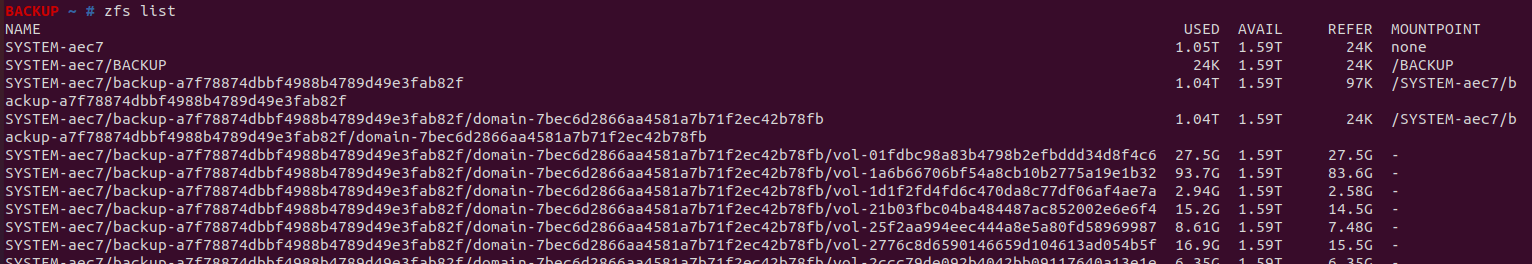
NAME: Name of the ZFS dataset (file system, volume, or snapshot).
USED: Amount of space used by the dataset, including its descendants (e.g., snapshots and children).
AVAIL: Amount of space available for use by the dataset and its descendants.
REFER: Amount of space used by the dataset itself, excluding descendants.
MOUNTPOINT: The directory where the dataset is mounted (if applicable).
Why do you get different results for df -h and zpool?
df -h is OS-level information, interpreting each dataset as if it were a traditional filesystem, zpool list shows the pool-wide usage and availability.
The values differ between df -h, zfs list, and zpool list because:
df -h shows the logical filesystem usage at the mount point level, which doesn’t factor in ZFS-specific features like snapshots or compression.
zfs list provides ZFS-specific metrics, giving a deeper look at each dataset’s physical storage use and how much space is referenced within the ZFS system.
zpool list gives an aggregate view of the entire pool, showing both allocated and free space for the pool as a whole.
Let’s take a closer look at zfs list command now.
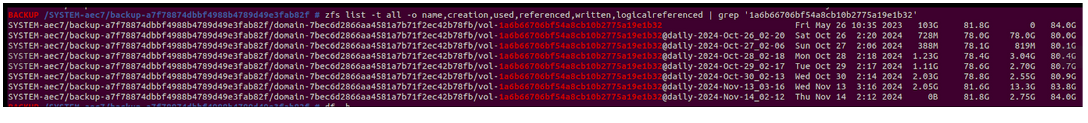
For example, let’s say we have VPS with uuid: 1a6b66706bf54a8cb10b2775a19e1b32. We can use zfs list command to retrieve a filtered list of ZFS datasets, snapshots, and other objects matching a specific string (1a6b66706bf54a8cb10b2775a19e1b32) in their names and we can do that with command:
zfs list -t all -o name,creation,used,referenced,written,logicalreferenced | grep '1a6b66706bf54a8cb10b2775a19e1b32'
Explanation of the command:
zfs list: Lists ZFS datasets, such as filesystems, snapshots, and volumes.
-t all: Specifies the types of ZFS objects to list. all includes file systems, volumes, and snapshots.
-o name,creation,used,referenced,written,logicalreferenced: Limits the output to these properties:
name: The name of the dataset.
creation: The creation date and time of the dataset.
used: The amount of space consumed by the dataset and its descendants.
referenced: The amount of space directly used by the dataset itself.
written: The amount of data written to the dataset since its most recent snapshot.
logicalreferenced: The logical size of all referenced data before compression and deduplication.
| grep '1a6b66706bf54a8cb10b2775a19e1b32': Filters the output, showing only lines where the dataset name contains the string 1a6b66706bf54a8cb10b2775a19e1b32.
Result:
Explanation:
Dataset name:
SYSTEM-aec7/backup-a7f78874dbbf4988b4789d49e3fab82f/domain-7bec6d2866aa4581a7b71f2ec42b78fb/vol-1a6b66706bf54a8cb10b2775a19e1b32@daily-2024-Nov-14_02-12
This represents a snapshot of a specific volume within a backup hierarchy. Each level indicates a nested dataset structure that ZFS uses for organization.
creation (Thu Nov 14 2:12 2024):
This snapshot was taken on November 14, 2024, at 2:12 AM. The timestamp indicates when this point-in-time copy of the dataset was made, which is helpful for backup retention and identifying the snapshot's relative age.
used (0B):
This indicates that the snapshot itself is currently using no additional physical storage. This is common when the snapshot doesn’t differ significantly from the current state of the dataset (i.e., no new blocks have been written since the snapshot was taken).
referenced (81.8G):
This is the amount of space used by the dataset itself at the time the snapshot was taken, totaling 81.8 GB. This value represents the storage occupied solely by this dataset without including space for other snapshots or dependent datasets.
written (2.75G):
This shows that 2.75 GB of data has been written to the dataset since the previous snapshot. This value can be useful to understand data changes over time, especially in incremental backups or sync processes.
logicalreferenced (84.0G):
The logical referenced size is 84.0 GB, which represents the amount of uncompressed data accessible within this snapshot. This shows the data size before any ZFS compression, giving you an idea of the original dataset size.
Conclusion
The difference in storage usage shown on the Hosts page and under Backup → Schedule in SERVERware is expected when Backup to ZFS is used.
The Hosts page and the df -h command display OS-level filesystem usage, which does not accurately represent real backup consumption in ZFS, since backups are stored as ZFS volumes and snapshots, not as regular files.
For accurate backup storage information:
zpool list shows the actual pool-level storage usage and matches the values shown in Backup → Schedule.
zfs list provides detailed information about individual datasets and snapshots.
If storage usage appears low on the Hosts page but higher in the Backup section, this does not indicate an issue. ZFS-specific tools should always be used as the authoritative source for backup storage usage.